The problem
Imagine three bank branches that each keep their own copy of every customer's balance. A wire comes in at Branch A. Before Branch A can tell the customer "done," it needs Branch B or C to agree the money actually moved. If it doesn't wait, and Branch A's power goes out a second later, the customer could end up seeing money that only exists in one branch's ledger, or a transfer that's only half-finished.
Now cut the phone lines between Branch C and the other two. Branch C can't confirm anything with anyone. Does it keep taking deposits on its own and hope the numbers reconcile later? Or does it refuse service until it can talk to someone again?
This project is a small distributed ledger: three replicated nodes, each backed by its own Postgres instance. It answers that question the second way. It picks correctness over uptime every time, and it's built so that choice is enforced by the system itself, not by hope.
Why it matters
This isn't an academic exercise. It's the tradeoff I've run into building payment infrastructure: the moment you're moving real money, "eventually consistent" stops being a performance optimization and starts being a liability. A remittance platform that briefly shows a wrong balance, or double-processes a transfer because two servers each thought they were the source of truth, doesn't just get a support ticket. It gets a compliance incident.
Most backend engineers can recite CAP theorem. I could too, before I'd actually had to decide, under a real outage, which side of it a system falls on. That's the part I hadn't really done before this project: building the mechanism, not just the policy, that makes the decision automatic instead of relying on someone's judgment at 3am. That's what this project tries to demonstrate: a system that detects its own isolation and shuts its own door, without a human in the loop. I'm not claiming I got every part of this right, and I've tried to be honest below about the parts I'm least sure of.
Key design decisions
Quorum, not a leader. The cluster runs N=3 nodes with W=2 (writes need 2 acks) and R=2 (reads check 2 nodes). Because R+W=4 is greater than N=3, every read is guaranteed to overlap with at least one node that saw the latest write. That's the whole trick behind strong consistency without a single elected leader. The tradeoff is that no fixed primary means any node can coordinate a write. That's simpler operationally, but it also means every write pays a fan-out cost that a leader-based design (Raft, for instance) could sometimes avoid.
Write acks any 2 of 3  →  {A,B}   {A,C}   {B,C}
Read checks any 2 of 3 →  {A,B}   {A,C}   {B,C}

Pick any write pair and any read pair from {A, B, C}. With
only 3 nodes total, two 2-node sets can never be disjoint.
They always share at least one node, and that node is
guaranteed to have seen the latest committed write.
R + W = 4 > N = 3 is just this pigeonhole argument, generalized.
Two-phase commit for replication. The naive version of this system, where the coordinator writes locally and then fires updates at peers, has an obvious failure mode. The coordinator can crash after committing locally but before a peer acknowledges, and now the nodes disagree about how much money exists. For a ledger, that's not a bug. It's the whole system failing at its one job. 2PC closes that hole. A PREPARE phase stages the transaction on peers first, and only once a quorum has acknowledged "ready" does the coordinator promote it to committed. The cost is honest too: every write now takes an extra network round-trip, and there's no recovery coordinator for a crash mid-2PC. A timed-out PREPARE is simply rolled back. That's a deliberate simplification. For a ledger, "safely did nothing" is always an acceptable outcome. "Silently half-did something" never is.
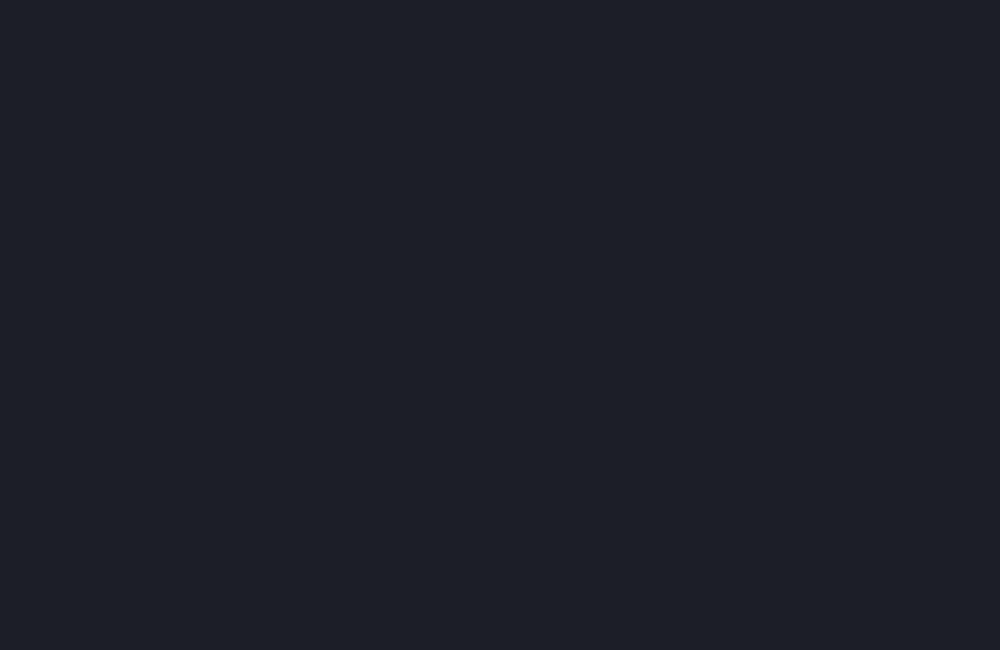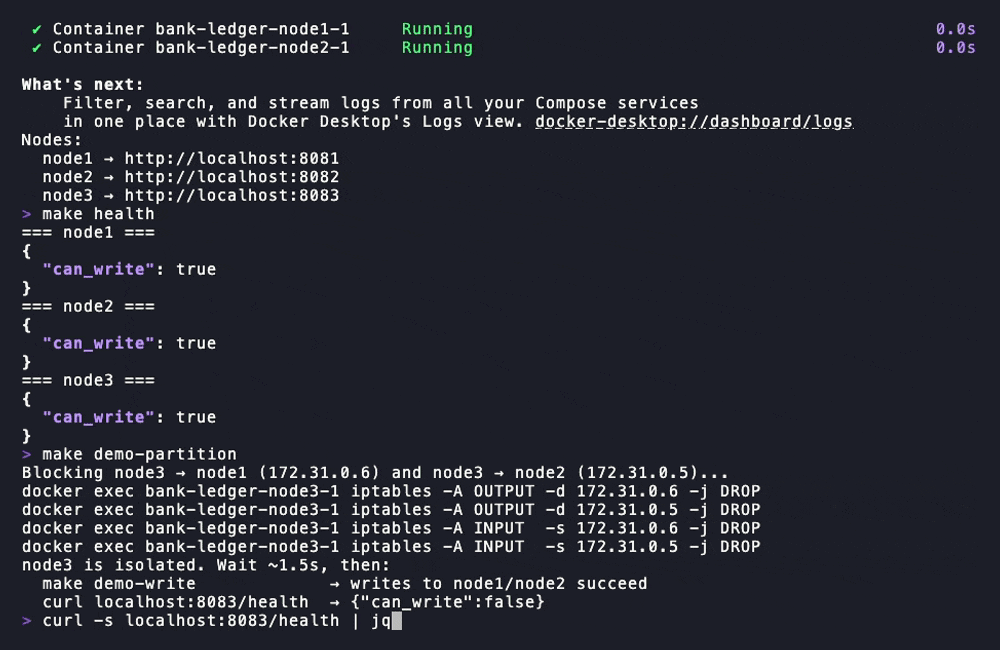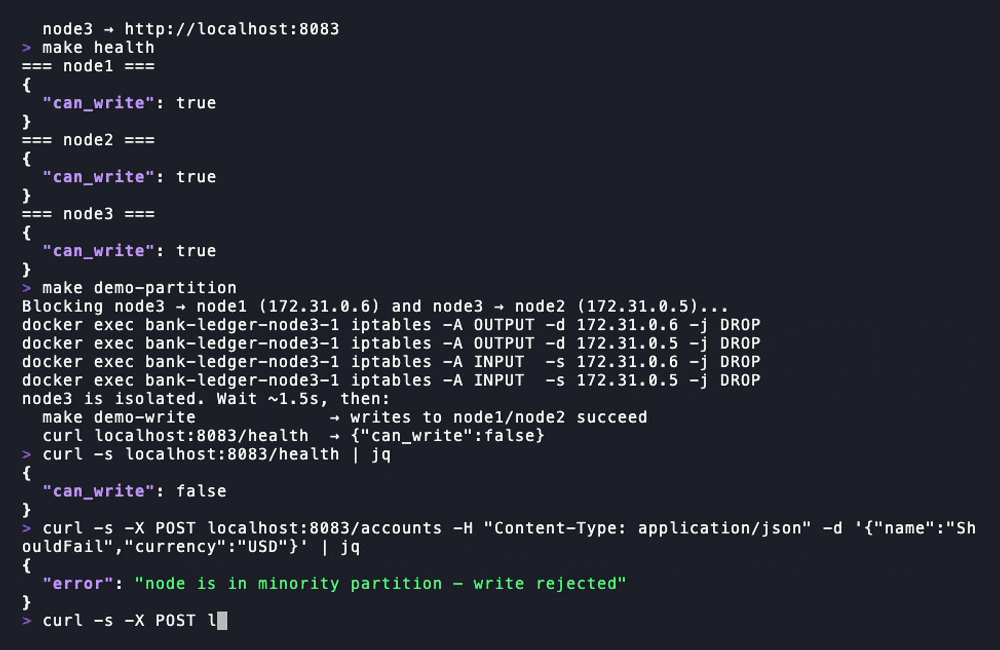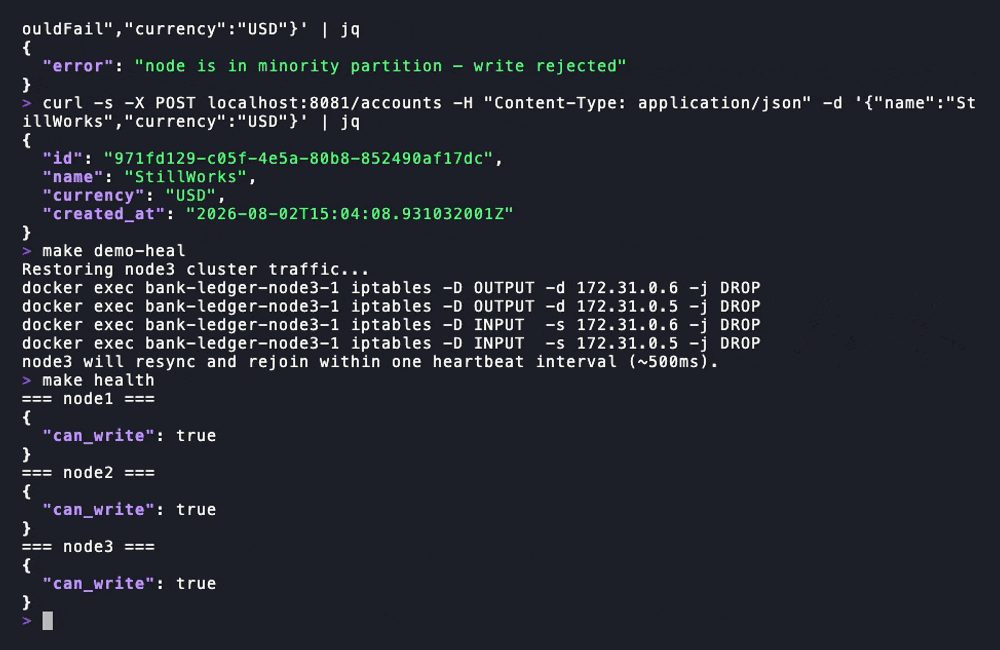
Eager heartbeat detection, not failure-on-write. Rather than waiting for a write to fail before realizing it's isolated, each node pings its peers every 500ms and flips a canWrite=false flag after 3 consecutive misses (~1.5 seconds). This is the mechanism that answers the Branch C question from the opening: the isolated node stops accepting writes proactively, before a client ever sends one, rather than accepting a write it can't safely commit and rejecting it after the fact.
Incremental resync on recovery. A node coming back from isolation is stale by definition. Before it's allowed to serve a single read or accept a write, it pulls everything it missed from a reachable peer and blocks until it's caught up. canWrite doesn't flip back to true until resync completes. The alternative, letting it rejoin immediately and catch up in the background, is faster to recover from, but it means a client could hit the just-recovered node and get a stale balance. I chose correctness over recovery speed here, to stay consistent with the rest of the system's stance.
This is the Branch C question from the opening, played out as a timeline:
t=0ms      Cable gets cut. Node3 can no longer reach node1 or node2.
             |
t=500ms    Node3 pings its peers → no response (miss #1)
t=1000ms   Node3 pings its peers → no response (miss #2)
t=1500ms   Node3 pings its peers → no response (miss #3)
             |
             v
           canWrite = false
           Node3 now rejects every write with 503, on its own,
           before a single client ever hits the problem.
             .
             .   (node1 + node2 still hold quorum, the ledger
             .    keeps taking writes; node3 just isn't part of it)
             .
t=Xms      Cable gets reconnected.
             |
t=X+500ms  Node3's heartbeat reaches node1/node2 again
             |
             v
           resync()
           Node3 pulls every transaction committed since its own
           last known committed_at from a live peer, and blocks.
             |
             v
           canWrite = true
           Only when it's caught up, not just reconnected,
           does node3 rejoin quorum and serve writes/reads again.
Double-entry accounting with no mutable balance column. Every transfer writes exactly one DEBIT and one CREDIT row inside a single DB transaction. Balance is always derived as SUM(credits) - SUM(debits), never stored and mutated directly. This isn't really a distributed-systems decision, it's an accounting one. But it's what makes the distributed guarantees actually mean something. A quorum-consistent ledger that stores a mutable balance is still one race condition away from creating or destroying money.
What I'd do differently
The resync mechanism doesn't quite match its own design, and I think that gap is instructive on its own. The design calls for resync by monotonic seq number (after_seq=N), which is the more correct approach. What's actually implemented uses a committed_at timestamp watermark (postgres.go). Timestamp-based resync is vulnerable to clock skew between nodes in a way sequence-based resync isn't. If a recovering node's clock is even slightly ahead of a peer's, it could compute the wrong catch-up window and silently miss a transaction. It's the kind of gap that's easy to miss in a demo, where it's three containers on one laptop with clocks in sync by default, and dangerous in production, with real nodes and real clock drift. If I extended this project, closing that gap (actually resyncing on seq, which already exists as a column) would be first on my list.
seq isn't globally ordered. It's assigned per-coordinator, not by a single sequencer. That's an accepted simplification for this scope. With three nodes and infrequent concurrent writes it doesn't bite in practice, but it means I wouldn't defend this design at higher write concurrency or larger N without revisiting it.
No crash-recovery coordinator for mid-2PC failures. This is an accepted tradeoff too. A coordinator that dies between PREPARE and COMMIT leaves the transaction to time out and roll back, rather than being resumed by another node. It's safe, but it means a coordinator crash always costs you the in-flight transaction. A production system might want a peer that can adopt and finish an in-doubt transaction instead of always discarding it.
Static N=3, no dynamic cluster membership. Adding or removing a node means redeploying with new peer addresses, not a live reconfiguration. Fine for a portfolio cluster, not fine for an operator who needs to scale nodes without downtime.
No transport security. Inter-node RPCs and the public API are plain HTTP. For anything beyond a local demo this needs mTLS between nodes at minimum.
None of these are things I discovered too late. They're the honest edges of a project scoped to demonstrate CP mechanics clearly, not to be production-hardened. I'd rather name them here than have someone else find them first. I'm still learning a lot of this as I build it, so if you've worked on something similar and see a tradeoff differently, I'd genuinely like to hear it.
Try it yourself
This is the same partition/heal cycle described above, recorded straight off a running local cluster. It's not a mockup:
git clone https://github.com/riorhezaharris/bank-ledger
cd bank-ledger
make up            # starts 3 nodes + 3 Postgres instances
make health        # confirm all three report {"can_write": true}
make demo-partition  # isolate node3 and watch it reject writes in real time
make demo-heal       # heal the partition and watch resync happen before it rejoins
The full API reference and architecture diagram are in the repo README.
If you clone it and find a way to break the quorum, or you'd have handled the resync gap differently, open an issue or reach out. I'd rather find out from you than assume I already thought of everything.